Beyond the Estimate: What Happens When PostgreSQL Index Advisors Meet Real-World Benchmarks
October 6, 2026
4 min read
Main Facts: The Illusion of Cost Reduction in Database Optimization
For database administrators and backend engineers managing high-throughput PostgreSQL deployments, query optimization is a perpetual high-stakes game. When a query crawls, the standard prescription is straightforward: find the missing index, create it, and watch performance recover. To automate this labor-intensive process, a new wave of open-source tools has emerged, promising automated index recommendations.
Among these is PgLens, an open-source PostgreSQL index advisor developed by software engineer Prateek Arora. Like many tools in its class, PgLens relies on HypoPG, a popular PostgreSQL extension that allows developers to create hypothetical indexes without consuming disk space or locking tables. This enables the database planner to run EXPLAIN statements against a simulated schema, estimating the performance impact of a proposed index before a single byte of storage is allocated.
If the planner estimates a cost reduction of 15% or more, the recommendation is flagged as valid. But Arora wanted to push past theoretical estimates to answer a fundamental question: What is that estimated percentage actually worth in wall-clock time?
When Arora put PgLens to the test using the rigorous Join Order Benchmark (JOB)—a dataset notorious for exposing the limitations of query optimizers—the results revealed a startling dichotomy. While the PostgreSQL planner proved remarkably accurate at identifying which queries stood to benefit most from indexing, its numerical cost estimates were frequently detached from physical reality. In some cases, following an advisor’s advice made queries up to eight times slower, while physical limits like maximum B-tree entry sizes caused silent failures that hypothetical engines could never predict.
Chronology: Putting Automated Index Advice to the Test
The journey from a theoretical index advisor to empirical benchmarking required a structured, methodical approach.
Phase 1: Building the Advisor and Integration with HypoPG
During the initial development of PgLens, Arora designed the system to ingest database query workloads, analyze execution statistics, and identify optimization opportunities. Following industry best practices, the engine utilized HypoPG to test prospective B-tree indexes.
The mechanism was standard:
- Identify a slow-running query from the workload history.
- Generate a candidate index based on column usage in filters and joins.
- Instruct HypoPG to construct a hypothetical index.
- Execute an
EXPLAINplan to check the planner’s revised cost estimation. - Retain suggestions that promised a cost drop of at least 15%.
Phase 2: Moving from Theory to Physical Execution
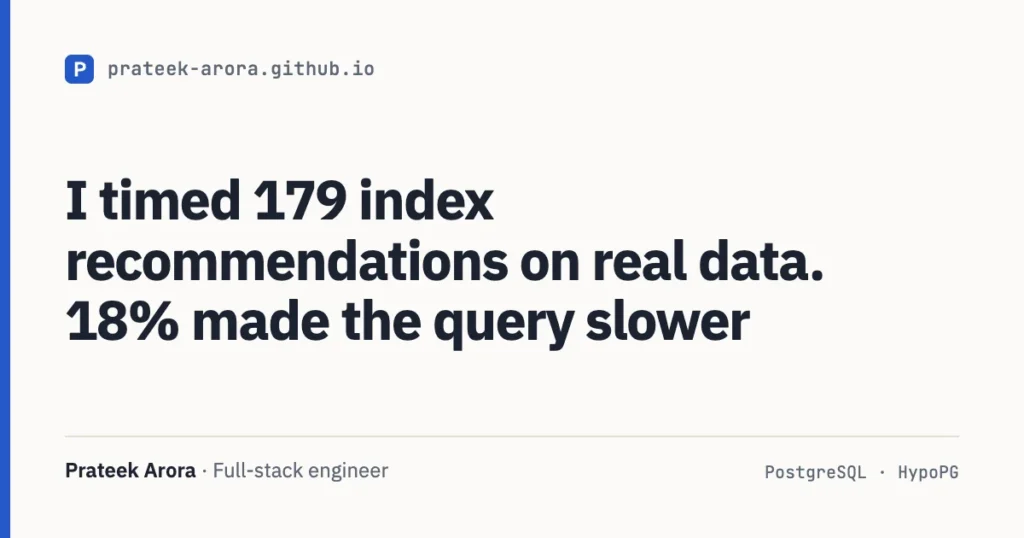
Recognizing that cost metrics are abstract units rather than seconds on a clock, Arora decided to test the validity of the tool’s output. Instead of trusting the planner’s forecast, every recommended index was built for real on a benchmark database instance, and the affected queries were physically timed before and after implementation.
Out of 179 measured index recommendations across the Join Order Benchmark:
- 128 indexes successfully accelerated query execution.
- 19 indexes resulted in no clear performance change.
- 32 indexes actively degraded query performance, making the system slower.
Phase 3: Analyzing Failures and Refining the Engine
Faced with dozens of regressions, Arora dug into the execution plans to understand why optimizations backed by the PostgreSQL planner failed so drastically in practice. The findings exposed inherent blind spots in cost-based optimization that affect not just PgLens, but any index advisor built on top of hypothetical execution planning.
Supporting Data: The Anatomy of a Performance Regression
To understand the limits of automated index advice, one must examine the specific failure modes uncovered during the Join Order Benchmark stress test.
The Cost Estimation Fallacy: Query 10c
The most extreme regression occurred during Query 10c, which involved an index created on the movie_id column of the cast_info table.
- The Planner’s Forecast: HypoPG and the PostgreSQL cost-based optimizer estimated that the index would reduce query cost by 91%, projecting a massive performance win.
- The Physical Reality: Before the index was built, the query executed in 0.93 seconds. After the index was physically created, execution time spiked to 7.3 seconds. When run manually to verify reproducibility, the runtime jumped from roughly 1 second to 9 seconds—an eightfold slowdown.
Why Did the Planner Fail?
The root cause lies in how the PostgreSQL planner estimates cardinality (row counts) during complex multi-table joins. With the index present, the optimizer abandoned its previous execution strategy in favor of a nested loop join that probed the cast_info table once for every row generated by the upstream join.
However, the planner severely underestimated the actual number of rows returned by that join. Because the cardinality estimate was wrong, the nested loop executed far more frequently than anticipated. The physical consequence was devastating: the query read 71 times as many database buffers as it did without the index.
Because HypoPG relies entirely on the native PostgreSQL planner using the exact same statistics, it shares the same cardinality blind spots. No advisor leveraging hypothetical indexes can catch this failure mode natively, because the underlying engine itself is blind to the cascading estimation error until runtime.
The B-Tree Size Limit Trap
Beyond query regressions, physical constraints posed another unexpected challenge. Out of the benchmark runs, 34 recommendations failed due to a structural limitation in PostgreSQL’s B-tree implementation. Specifically, PgLens’s second-highest priority suggestion—an index on movie_info (info)—triggered the following fatal database error:
ERROR: index row requires 9392 bytes, maximum size is 8191Upon investigation, it was revealed that 1,182 out of 14.8 million data values exceeded the maximum allowable size for a B-tree index entry. Because a hypothetical index never actually writes data to disk, HypoPG cannot detect when a dataset violates physical storage limits. A tool relying solely on simulation has no way of knowing a write will fail until an engineer attempts to build the index in production.
Official Responses and Empirical Insights: What the Planner Got Right
Despite the alarming regressions and physical limitations exposed by the benchmark, the data also highlighted where the PostgreSQL planner excels.
The Power of Ranking
While the percentage of estimated cost reduction proved largely unreliable for predicting wall-clock speedups, the relative ranking of index suggestions was remarkably accurate.
When evaluating the overall workload, PgLens’s top-ranked index recommendation alone accounted for saving 364 seconds out of the 424 total seconds consumed by the target queries. Furthermore, a statistical analysis of the index ranking order against measured savings yielded a Spearman correlation coefficient of 0.83, indicating a strong alignment between what the planner thought was important and what actually moved the needle.
The takeaway for database tooling developers is clear:
- Asking the planner "Which index matters most?" yields highly reliable, actionable intelligence.
- Asking the planner "How much faster will this query get?" invites false precision and misleading expectations.
Implications: The Future of Automated Database Tuning
The findings from the PgLens Join Order Benchmark have profound implications for the ecosystem of database management systems, automated tuning agents, and AI-assisted infrastructure tools.
1. The Limits of Simulation
As organizations increasingly turn to automated Database Administration (DBA) tools and AI-driven schema optimizers, the industry must recognize that simulation is not a substitute for empirical testing. Hypothetical index tools are invaluable for narrowing down a vast search space of potential schemas, but they cannot replace the ground truth of runtime execution.
2. Guardrails for Modern Advisors
In response to these benchmarks, developers of automated index advisors must incorporate robust safety mechanisms:
- Pre-flight Validation Checks: Ensuring that column data types and value lengths comply with storage constraints before attempting index creation.
- Staging Environment Verification: Moving beyond dry-run cost estimates by automatically timing indexes on isolated database replicas before recommending them for production deployment.
- Regression Monitoring: Equipping tools to automatically roll back indexes if post-creation runtime telemetry detects an increase in buffer reads or execution latency.
3. Open Source Transparency
Arora’s decision to open-source the entire benchmark methodology, raw datasets, and evaluation scripts under the Apache-2.0 license sets a high standard for engineering accountability in the database tooling space. Built with assistance from AI coding assistants like Claude Code, the repository serves as an open invitation for the broader database community to audit, critique, and improve upon the mechanics of automated query tuning.
Try It and Contribute
For engineers looking to audit their own database workloads or experiment with transparent, self-hosted index advising, PgLens is available as a release candidate.
The project remains strictly read-only regarding production data safety. It ranks workloads by real execution times, cross-checks suggestions with the planner, and offers staging-copy timing features to catch regressions before they reach production.
- GitHub Repository: github.com/Prateek-Arora/pglens
- Benchmark Methodology & Scripts: docs/benchmarks.md
With just a few make commands from the README, developers can spin up a self-hosted demo featuring a slow query workload in approximately three minutes. As the project matures toward a stable release, developer feedback and edge-case bug reports—especially those that expose flaws in the advisor’s logic—are actively welcomed by the maintainer.