Balancing the Scales: How to Run High-Performance Analytics on PostgreSQL Without Sacrificing Operational Speed
VALENCIA, Spain — In the modern data ecosystem, database administrators and software architects often find themselves trapped between competing demands. On one side are the fast-paced, high-frequency needs of daily transactional applications—Online Transaction Processing (OLTP)—which demand lightning-fast writes, low latency, and unwavering stability. On the other side is the insatiable appetite for business intelligence, reporting, and historical analysis—Online Analytical Processing (OLAP)—which requires crunching massive volumes of data, expensive aggregations, and complex sorting operations.

Historically, these two workloads lived in completely separate universes. Organizations maintained operational databases for day-to-day app processing and laboriously extracted data via nightly or weekly batch jobs into dedicated data warehouses. Today, however, many businesses want to bridge this divide. They want real-time insights directly from their operational data stores without spinning up complex, expensive parallel architectures.

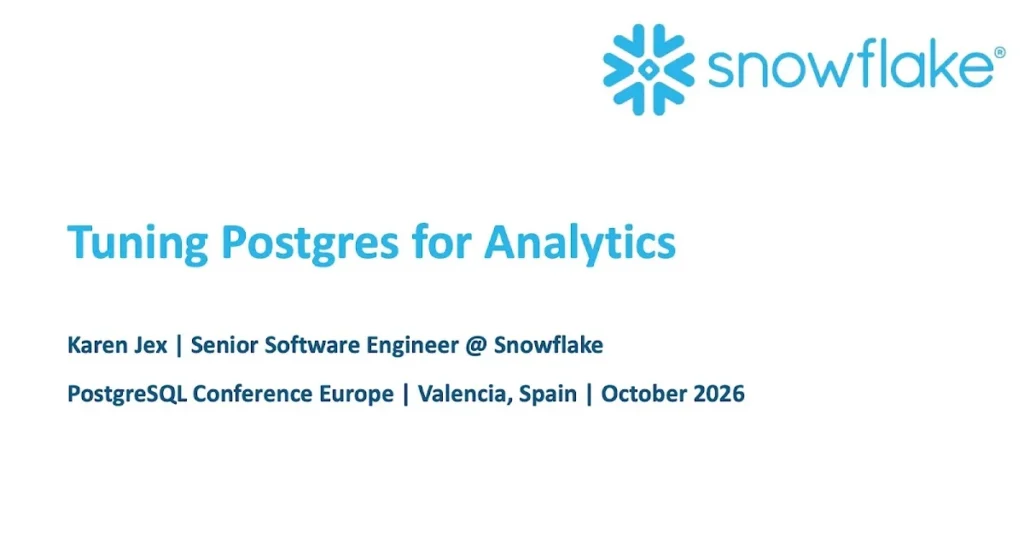
At PostgreSQL Conference Europe (PGConf.EU) in Valencia, Karen Jex, a Senior Software Engineer on the Postgres extensions team at Snowflake and a prominent figure in the PostgreSQL Europe community, took center stage to address this exact challenge. In her comprehensive session, "Tuning Postgres for Analytics," Jex explored the real-world mechanics of Hybrid Transactional/Analytical Processing (HTAP), breaking down practical techniques for database optimization, query tuning, and workload isolation.

The Core Dilemma: Why OLTP and OLAP Collide
To illustrate the friction between transactional and analytical workloads, Jex invited the audience to imagine a relatable scenario: running a small, highly successful chain of popular coffee shops in Valencia, Spain.

The business relies on a state-of-the-art backend system managing sales, stock, and a customer loyalty program. Over years of successful operation, this system has accumulated millions of rows of transaction data. Day-to-day operations hum along smoothly because the production database has been carefully tuned for the application’s immediate workload.

However, management eventually demands deeper insights to plan future promotions. They ask a classic business intelligence question: "Which Valencia location had the highest total sales for each month of last year, counting only transactions with a value greater than €20?"

To answer this, an analyst writes a complex SQL query utilizing window functions, date truncations, groupings, and arithmetic calculations across millions of rows. On an otherwise quiet database, the query executes in roughly five seconds. But when run against a live system under a heavy transactional workload, the story changes dramatically.

The Anatomy of Interference
Why do long-running analytics queries drag down operational applications? Jex highlighted several key performance bottlenecks:

- Buffer Cache Pollution: Heavy analytical scans read massive blocks of data into shared memory, often pushing hot transactional pages out of the cache and forcing expensive disk reads.
- Resource Contention: OLAP queries frequently consume high amounts of CPU, memory, and Input/Output (I/O) bandwidth, starving concurrent transactional requests.
- Locking and Concurrency Overhead: Complex joins and aggregations can exacerbate locking conflicts, lengthening transaction queues and degrading application responsiveness.
To empirically measure this interference, Jex utilized pgbench, a standard benchmarking tool built into PostgreSQL. Initializing a test environment with a scale factor of 50 yielded 50 branches, 500 tellers, and 5 million rows in the pgbench_accounts table (~750MB). Running a mixed workload simulation demonstrated an immediate degradation in transactions per second (TPS) and a noticeable spike in query latency, confirming the academic consensus established by database benchmarks like CH-benchMark and M2Bench over the past decade.

Chronology of Optimization: From Raw Queries to Materialized Architecture
Faced with a mixed workload environment where a separate, dedicated analytics warehouse is unavailable, database administrators have a sliding scale of architectural and configuration options to mitigate performance degradation. Jex outlined a chronological progression of tuning strategies, starting with minor configuration tweaks and advancing to sophisticated lakehouse integrations.

Phase 1: Database Configuration and Resource Controls
The first line of defense involves modifying PostgreSQL configuration parameters (postgresql.conf) and session-level settings to prevent analytical queries from monopolizing system resources.

work_memManagement: The defaultwork_memsetting in PostgreSQL is a modest 4MB. When a query exceeds this limit during sorting or hashing operations, it spills to disk, generating slow temporary files (evident in execution plans asSort Method: external merge). By temporarily increasingwork_memfor specific analytical sessions, administrators can accelerate complex queries—provided they strictly limit the number of concurrent analytical users to avoid running out of system RAM.- Connection Pooling with PgBouncer: High connection counts create excessive server overhead. Implementing connection poolers like PgBouncer allows administrators to isolate analytical users into a separate, tightly capped connection pool, protecting the primary application from connection exhaustion.
- Statement Timeouts: To prevent runaway analytics scripts from locking up system resources indefinitely, administrators can enforce a strict
statement_timeouton the analytics role, ensuring problematic queries automatically abort after a predefined window.
Phase 2: Indexing Strategies and Generated Columns
Indexing is vital for accelerating query filtering, but over-indexing an operational database penalizes write-heavy OLTP workloads. Jex emphasized the need for a precise balance:

- Indexes on Expressions: By creating indexes on scalar expressions or functions (such as the total sale amount calculation used in the demo query), the PostgreSQL query planner can utilize bitmap index scans, slashing execution times from seconds down to fractions of a second.
- Stored Generated Columns: Introduced in modern PostgreSQL versions,
GENERATED ALWAYS AS (...) STOREDcolumns allow developers to physically store calculated expressions directly within the table structure. These generated columns can then be indexed natively, reducing query-time CPU overhead at the minor expense of insert performance.
Phase 3: Pre-Aggregating Data with Materialized Views
When raw, real-time data access isn’t strictly mandatory, materialized views offer a powerful shortcut. A materialized view acts as a physical snapshot of a query’s result set, complete with its own indexes.

Jex demonstrated how converting the expensive ranking subquery into a materialized view dropped query execution times from several seconds down to a few milliseconds. Because materialized views can become stale as new transactional data arrives, administrators must schedule periodic background refreshes—often leveraging extensions like pg_cron during off-peak hours to minimize operational impact.

Supporting Data and Technical Implementation
During the presentation, Jex walked through concrete code examples to demonstrate how these strategies are implemented in production environments.

For instance, optimizing the cafe sales schema began with a standard operational table definition:

CREATE TABLE cafe_sales (
    transaction_id NUMERIC,
    transaction_date DATE,
    transaction_time TIME,
    transaction_qty NUMERIC,
    store_id NUMERIC,
    store_location TEXT,
    product_id NUMERIC,
    unit_price NUMERIC,
    product_category TEXT,
    product_type TEXT,
    product_detail TEXT,
    sales_tax_pct NUMERIC
);
By leveraging generated columns and materialized views, the heavy lifting of calculating totals, applying tax percentages, and ranking store performance was shifted away from runtime execution. Furthermore, integrating tools like pg_cron allowed for automated, hourly refreshes of analytical data structures without manual intervention.

Official Responses and Industry Evolution: Enter the Lakehouse
While internal database tuning and materialized views solve many mixed workload problems, scaling to extreme data volumes eventually requires shifting analytical queries off the primary application server entirely.

Jex detailed traditional scaling pathways, including Physical Replication (which creates an exact read-only byte-for-byte copy of the primary database but restricts custom schema modifications or isolated indexing) and Logical Replication (which permits selective table replication to a dedicated subscriber database, allowing administrators to build custom materialized views, users, and indexes strictly for analytics).

However, modern data engineering has introduced an even more compelling frontier: bridging PostgreSQL with open storage formats like Apache Iceberg and Parquet.

Bridging Postgres and Data Lakes with pg_lake
Addressing the common enterprise pain point of fragmented data silos, Jex highlighted an innovative open-source solution: pg_lake. Originally developed by Crunchy Data and open-sourced by Snowflake, pg_lake is an interdependent suite of PostgreSQL extensions that effectively transforms a standard Postgres instance into a standalone lakehouse architecture.

By enabling pg_lake, PostgreSQL can act as an Apache Iceberg catalog while leveraging DuckDB’s high-performance columnar query engine internally. This allows database engineers to create columnar Iceberg tables using simple SQL syntax (USING iceberg), join live transactional heap tables directly with external lakehouse files, and execute heavy analytics at lightning speed without moving data through complex, fragile external pipelines.

Implications and Decision Framework
Choosing the right optimization path depends entirely on an organization’s specific operational constraints. In her closing remarks, Jex provided a practical decision framework for database administrators facing analytical performance bottlenecks:

- Are your queries known and repeatable? If yes, leverage generated columns, targeted expression indexes, and pre-aggregated structures to smooth out performance spikes.
- Is stale data acceptable? If business intelligence users do not require second-by-second accuracy, offload analytical queries to materialized views refreshed on an hourly or daily schedule.
- Do you need workload isolation? If the primary application database is hitting capacity limits, implement dedicated analytical user roles with strict resource boundaries, or offload read traffic to physical and logical replicas.
- Are you dealing with external data lakes? If analytical models require querying massive datasets stored in Parquet or Iceberg formats, modern extension frameworks like
pg_lakeallow teams to "just use Postgres" as a unified query engine.
As PostgreSQL continues to evolve, the traditional walls separating transactional systems from analytical engines are steadily crumbling. Through careful configuration, strategic indexing, smart materialized view management, and modern extension tooling, organizations can successfully embrace HTAP architectures—empowering deep business insights while keeping their core applications running faster than ever.