The Evolution of Prompt Engineering: From Direct Instructions to Autonomous Agentic Workflows
Introduction
In the rapidly expanding landscape of artificial intelligence, two engineers can input the exact same query into a large language model (LLM) and receive entirely different outcomes: one might get a vague, useless generalization, while the other receives a precise, production-ready solution. More often than not, the disparity lies not in the underlying neural network architecture, but in the structural integrity of the prompt.
Prompt Engineering has evolved from an informal guessing game into a rigorous computational discipline. It is the practice of systematically designing input structures—instructions, contextual framing, explicit few-shot examples, and expected output schemas—to extract the most useful and reliable outputs from an LLM without modifying a single parameter of the model itself.
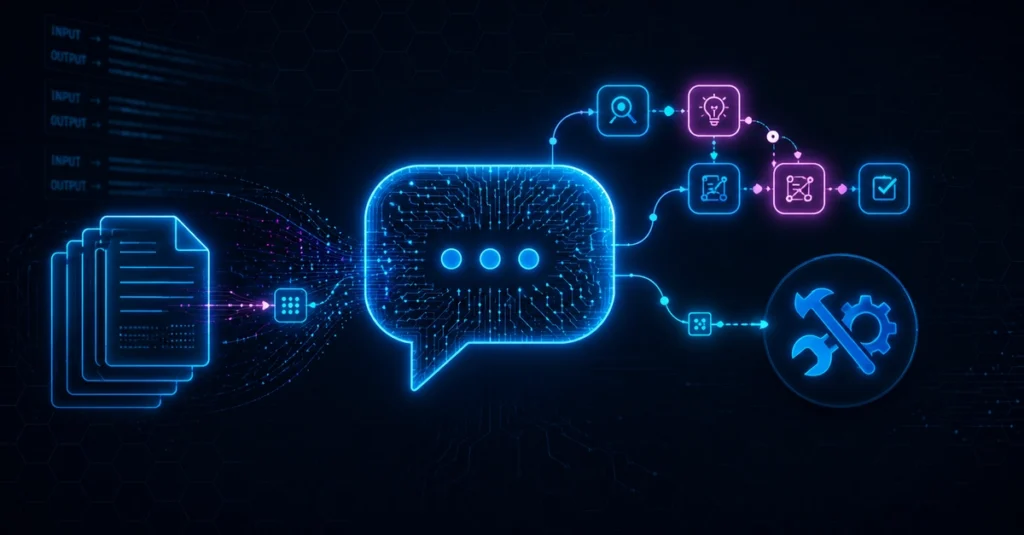
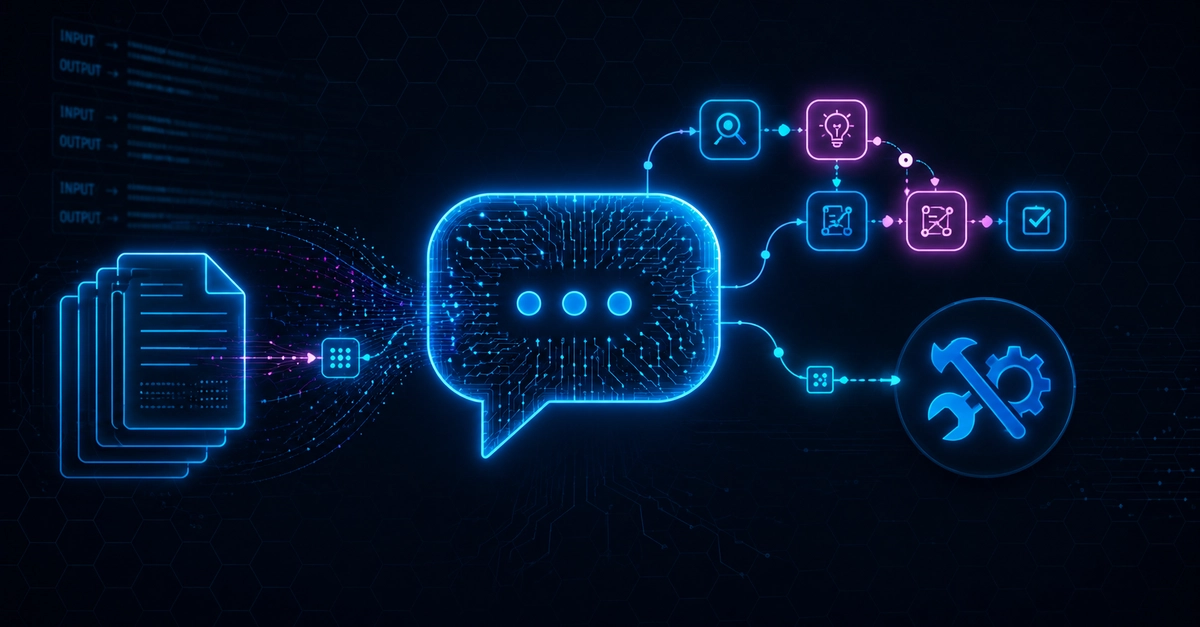
This field has matured at a breathtaking pace. It began with simple, direct instructions (zero-shot), progressed to providing inline templates (few-shot), learned to force models to "think out loud" (Chain-of-Thought), validated that logic through multi-path verification (self-consistency), and has now arrived at sophisticated paradigms connecting models to external vector databases (RAG) and dynamic execution tools (ART).
Below is a comprehensive exploration of these six core techniques, arranged in the order of the increasingly complex challenges they were engineered to solve.
Quick Overview: The Prompt Engineering Spectrum
| Technique | Core Problem It Solves | Context Cost |
|---|---|---|
| Zero-shot | Direct task execution without reference examples, relying purely on pre-training. | Minimal |
| Few-shot | Teaching the expected formatting and patterns via inline examples within the prompt. | Low to Medium |
| Chain-of-Thought (CoT) | Enhancing multi-step logic and deduction in mathematics and abstract reasoning. | Medium |
| Self-consistency | Mitigating logical errors by running multiple parallel paths and aggregating results. | High (Multiple API calls) |
| RAG (Retrieval-Augmented Generation) | Grounding answers in current, private, or real-time enterprise data outside the training set. | Medium to High (Search + context) |
| ART (Automatic Reasoning and Tool-use) | Handling complex operations requiring exact arithmetic, external APIs, or real-world actions. | High (Tool orchestration) |
Each technique serves as a stepping stone, systematically bypassing the structural limitations of its predecessor.
1. Zero-Shot Prompting: Direct Instructions Without Examples
The Fundamentals
Zero-shot prompting represents the simplest interaction model with an LLM. The user describes a task in natural language and immediately requests a response, providing zero prior examples of how the output should look. This approach functions because modern LLMs have ingested billions of instances of diverse tasks during their pre-training phase, allowing them to generalize successfully from simple instructions.
Classify the sentiment of the text below as positive, negative, or neutral.

Text: "The customer service line took forever to answer, but the product arrived in pristine condition."
Sentiment:
When to Use and Limitations
Zero-shot is ideal for broad, well-understood tasks where the output format is flexible—such as general summarization, straightforward translation, or basic brainstorming.
However, zero-shot prompting breaks down when a task is ambiguous, requires a rigid, highly specific output format, or falls outside the model’s most common training distributions. When precision and structural adherence are paramount, engineers must transition to few-shot prompting.
2. Few-Shot Prompting: Calibrating via Examples
The Fundamentals
Few-shot prompting injects a handful of complete input-to-output examples directly into the prompt context window before presenting the target query. The model is not retrained or fine-tuned; rather, it uses these inline examples as an explicit template for pattern matching and structural alignment.
Classify the sentiment as positive, negative, or neutral.

Text: "It arrived ahead of schedule and completely blew away my expectations."
Sentiment: positive

Text: "I cancelled my subscription immediately; customer support never replied."
Sentiment: negative

Text: "The product is okay, nothing exceptional."
Sentiment: neutral

Text: "The customer service line took forever to answer, but the product arrived in pristine condition."
Sentiment:
Why It Works and Its Boundaries
This mechanism relies on in-context learning. The model does not update its permanent weights, but it dynamically uses the examples in the prompt to infer the expected formatting, tone, and decision criteria for that specific inference call.
While few-shot prompting dramatically improves output formatting, it fails when a task requires sequential, multi-step logical reasoning (such as complex word problems). Providing only final answers does not teach the model how to calculate or deduce the path to get there.
3. Chain-of-Thought (CoT): Forcing Explicit Reasoning
The Fundamentals
Formalized by Google researchers in 2022 (Wei et al.), Chain-of-Thought (CoT) prompting instructs or exemplifies that a model must expose its step-by-step reasoning process before arriving at a final conclusion, rather than jumping straight to the end result. CoT has demonstrated massive performance gains in mathematics, logical deduction, and multi-step problem solving.
Zero-Shot CoT
The simplest implementation requires no examples—merely appending a phrase like "Think step by step before answering" to the prompt:
A retail store started with 23 apples. They sold 8 in the morning and received a shipment of 15 more in the afternoon.
How many apples do they have now? Think step by step before answering.
Expected Model Output:
Step 1: The store started with 23 apples.
Step 2: They sold 8, leaving 23 - 8 = 15 apples.
Step 3: They received 15 more, resulting in a total of 15 + 15 = 30 apples.
Answer: 30 apples.
Few-Shot CoT
This variation combines CoT with examples, demonstrating complete reasoning chains inside the prompt context:
Question: John had 5 oranges, then bought 3 boxes with 4 oranges each. How many does he have in total?
Reasoning: John started with 5 oranges. Each box contains 4 oranges, and there are 3 boxes, so 3 x 4 = 12.
Total: 5 + 12 = 17.
Answer: 17

Question: A delivery van carries 12 passengers per trip and completed 4 trips today. How many total passengers were transported?
Reasoning:
Why It Works
LLMs generate text token by token, predicting the next word based on everything written previously—including what the model itself generated earlier in the response. By forcing intermediate reasoning steps into the generated text, each correct logical step serves as immediate context for the next, drastically reducing the probability of jumping to a premature, incorrect conclusion.
4. Self-Consistency: Voting Across Multiple Paths
The Fundamentals
Even when using Chain-of-Thought, an LLM can occasionally follow a plausible yet fundamentally flawed reasoning path, arriving at an incorrect answer with absolute confidence. Self-consistency addresses this vulnerability by generating multiple independent reasoning chains for the exact same query (utilizing a sampling temperature greater than zero to encourage divergent paths) and selecting the most frequent final answer via majority voting.
responses = []
for _ in range(5):
    response = llm.generate(
        prompt="Think step by step to solve this: " + question,
        temperature=0.7,  # Explores a different reasoning pathway per call
    )
    responses.append(extract_final_answer(response))

final_answer = max(set(responses), key=responses.count)
Why It Works
Logical errors in LLMs tend to be inconsistent across multiple execution runs—the model will fail in a different way each time. Conversely, correct reasoning paths consistently converge on the exact same mathematical or logical conclusion. Sampling multiple trajectories allows individual anomalies to cancel each other out.
However, standard prompting techniques still suffer from a fundamental barrier: models are inherently bounded by their static training data cutoff dates, leaving them blind to real-time events, private corporate databases, and exact programmatic computations.
5. Retrieval-Augmented Generation (RAG): Grounding in External Knowledge
The Fundamentals
Retrieval-Augmented Generation (RAG) marries external information retrieval systems with LLM text generation. Before an LLM attempts to answer a user’s query, the application queries an external vector database or search index for contextually relevant passages (such as internal company documentation, PDFs, or live web snippets) and injects those excerpts directly into the prompt. The model is then instructed to synthesize its response using only the provided context.
pergunta = "What is the corporate refund policy for canceled enterprise accounts?"

# 1 & 2: Semantic vector search against the internal knowledge base
trechos = base_vetorial.search(pergunta, top_k=3)

# 3: Constructing the augmented prompt with retrieved context
contexto = "n---n".join(trechos)
prompt = f"""
Answer the question using exclusively the provided context below.
If the answer cannot be found within the context, state clearly that you do not know.

Context:
contexto

Question: pergunta
"""

# 4: Generation grounded in the retrieved factual data
resposta = llm.generate(prompt)
Why It Works
RAG cleanly separates two distinct responsibilities that were previously tangled together:
- Knowledge (Factual Truth & Currency): Maintained within an external, updateable database that can be refreshed instantly without retraining weights.
- Language Synthesis (Coherence & Tone): Handled entirely by the LLM.
This architecture significantly dampens hallucinations, granting models secure, auditable access to private proprietary data and real-time facts.
6. Automatic Reasoning and Tool-Use (ART): Autonomous Agent Workflows
The Fundamentals
ART (Automatic Reasoning and Tool-use), formalized by Microsoft Research in 2023 (Paranjape et al.), pushes boundaries further by allowing models to dynamically decide when to invoke external tools during the reasoning loop—such as calling a calculator, executing Python code, querying a live API, or running a web search—and subsequently integrating those programmatic outputs back into their working memory. Today, this is widely recognized under the broader umbrellas of tool use or function calling.
ferramentas = [

        "name": "calculator",
        "description": "Evaluates a mathematical expression and returns the exact result.",
        "parameters": "expression": "string",
    ,

        "name": "fetch_exchange_rate",
        "description": "Returns the current live exchange rate between two fiat currencies.",
        "parameters": "base": "string", "target": "string",
    ,
]

resposta = llm.generate(
    prompt="If I convert 1,500 USD to BRL at today's live rate, "
           "and then invest 20% of that total at a monthly yield of 0.9% for 6 months, what is the final payout?",
    tools=ferramentas,
)

# The model autonomously orchestrates execution in sequence:
# 1. Calls fetch_exchange_rate("USD", "BRL") -> retrieves real-time pricing data.
# 2. Calls calculator("1500 * rate") -> performs exact currency conversion.
# 3. Calls calculator("(converted_val * 0.2) * (1.009**6 - 1)") -> computes compound interest.
# 4. Synthesizes the final human-readable response using verified programmatic outputs.
Why It Works
While LLMs excel at linguistic processing, they are historically unreliable at deterministic calculations, real-time data retrieval, and exact arithmetic. ART delegates orchestration and high-level reasoning to the model while outsourcing exact mathematical and computational execution to specialized programmatic tools.
Comparative Matrix: The Interconnected Prompting Ecosystem
| Technique | Primary Objective | Added Overhead | Limitation Addressed from Previous Methods |
|---|---|---|---|
| Zero-shot | Simple, well-known tasks | None | None |
| Few-shot | Specific output formatting and style matching | Context tokens (examples) | Zero-shot struggles with formatting or subtle criteria. |
| Chain-of-Thought | Multi-step logical reasoning | Reasoning generation tokens | Few-shot does not teach the model how to derive answers. |
| Self-consistency | Logical reliability and error reduction | Multiple API call cycles | CoT can occasionally follow a plausible but incorrect path. |
| RAG | Up-to-date or private factual knowledge | Retrieval index + context tokens | Models lack access to facts outside their static training cutoffs. |
| ART / Tool-use | Deterministic precision and real-world execution | Tool orchestration loops | LLMs cannot reliably calculate or act outside of static text generation. |
Production-grade AI assistants rarely rely on a single technique in isolation. Instead, they combine them: using few-shot examples to lock down output formatting, Chain-of-Thought for complex logic, RAG to ground responses in factual data, and tool-use for programmatic calculations.
Best Practices for Enterprise Prompt Engineering
- Start Simple, Scale Up: Begin with zero-shot prompting. Only introduce few-shot examples, Chain-of-Thought, or tool integrations when empirical testing proves the base model fails consistently.
- Explicitly Constrain Outputs: Always define fallback behaviors. For instance, instruct the model: "If the answer is not present in the provided context, state ‘I do not know’."
- Isolate Context from Instructions: Use clear delimiters (such as XML tags like
<context>and</context>or markdown triple backticks) to separate structural prompts from dynamic user data, preventing prompt injection vulnerabilities. - Iterate via Evaluation Datasets: Treat prompts like code. Maintain a regression test suite of diverse inputs to evaluate prompt changes systematically before deploying to production environments.
Conclusion
Prompt engineering is not about searching for a "magic phrase" or a secret combination of words. Rather, it is the deliberate diagnosis of a model’s operational limitations and the application of structural techniques designed to bypass those exact bottlenecks.
Zero-shot and few-shot calibration handle syntax and formatting. Chain-of-thought and self-consistency unlock logical reasoning and verification. RAG bridges the gap of missing corporate or real-time knowledge. Finally, tool-use and agentic workflows conquer the boundaries of text-only generation by interfacing with the physical and computational world.
Ultimately, robust AI applications rely on the strategic integration of these techniques. The true differentiator for prompt engineers lies in their ability to diagnose task complexity and orchestrate the precise mix of methods needed to ensure reliability at scale.