Unlocking Peak Performance: How TensorFlow Lite Slashed Memory Arena Overhead by Over 40%
By Alan Kelly, Software Engineer
Published in partnership with the TensorFlow Core Engineering Team
Main Facts: The Hidden Cost of On-Device Machine Learning Efficiency
Deploying machine learning (ML) models on edge devices—ranging from smartphones and wearables to microcontroller-driven IoT hardware—requires a delicate balancing act between memory consumption and execution speed. In a previous deep-dive, Optimizing TensorFlow Lite Runtime Memory, the TensorFlow engineering team detailed how TensorFlow Lite (TFLite) leverages a specialized "memory arena" to minimize memory footprints. By intelligently sharing buffers between tensors, TFLite allows massive deep-learning models to execute within the strict constraints of low-memory edge hardware.
However, memory efficiency has historically come with a hidden computational tax: initialization and runtime overhead.
In a recent performance audit of TFLite’s runtime execution on resource-constrained Android hardware, engineers discovered an alarming bottleneck. For complex models featuring dynamic tensors and variable input sizes—such as those found in real-time natural language processing and computer vision pipelines—up to 54.3% of the total runtime was being consumed not by heavy neural network operators (like convolutions or fully connected matrix multiplications), but by the memory arena allocator itself.

Through rigorous profiling using Android’s Simpleperf and pprof, followed by a series of targeted C++ algorithmic refactorings, the TensorFlow team successfully slashed this overhead. The resulting optimizations, officially released as part of TensorFlow 2.13, drastically reduce runtime overhead, returning the execution profile of edge-deployed models to what it should be: a heavy focus on math operations rather than memory bookkeeping.
Chronology: The Step-by-Step Optimization Journey
To understand how the TensorFlow engineering team untangled this complex performance knot, one must trace the chronological sequence of profiling sessions, counterintuitive discoveries, and code refactorings that defined the project.
Phase 1: Establishing the Baseline with Simpleperf
The optimization initiative began by moving away from theoretical code reviews and toward empirical, on-device profiling. Using representative data on a target development device connected via Android Debug Bridge (adb), the team employed Simpleperf—the native profiling tool built into the Android NDK.
The profiling workflow required executing custom binary testing scripts:

# Push and run simpleperf on the target device
/usr/lib/android-ndk/simpleperf/run_simpleperf_on_device.py record
  --call-graph fp /data/local/tmp/my_binary arg0 arg1 ...

# Pull the performance data back to the host machine
adb pull /data/local/tmp/perf.data

# Build the binary cache for symbol resolution
/usr/lib/android-ndk/simpleperf/binary_cache_builder.py -lib /your/binarys/folder -i perf.data

# Generate the protocol buffer for visualization
/usr/lib/android-ndk/simpleperf/pprof_proto_generator.py
  --ndk_path=/path/to/android-ndk -i perf.data -o profile.proto

# Launch pprof to visualize flame graphs
pprof -http :8888 profile.proto
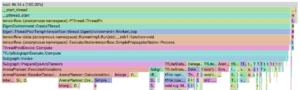
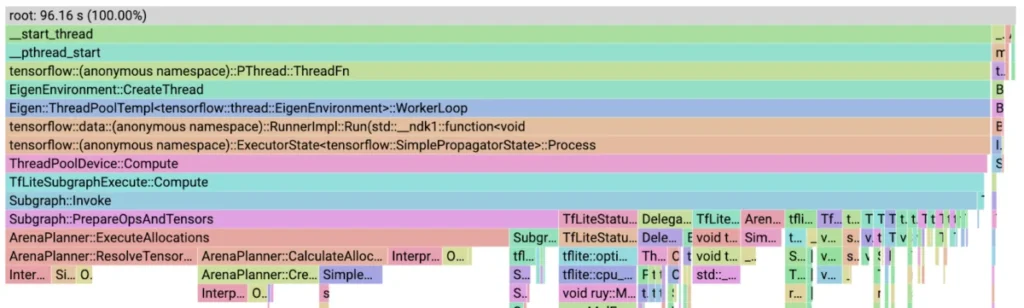
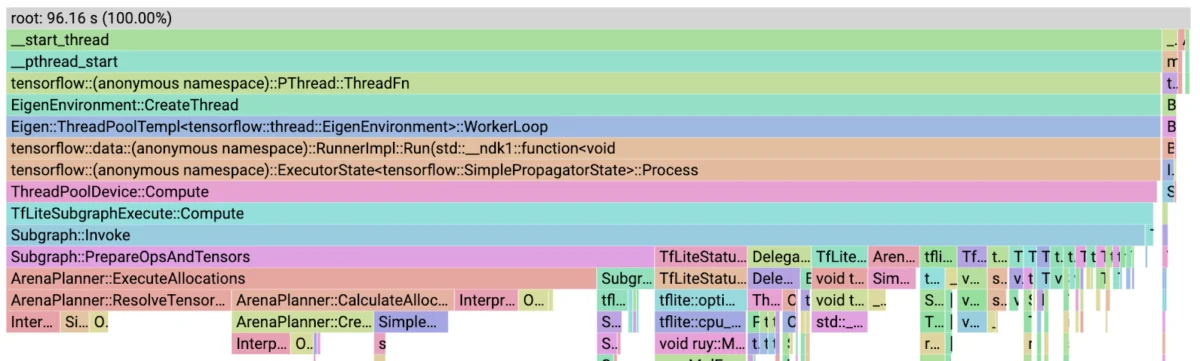
Upon opening the flame graph at localhost:8888, the initial findings were staggering. For models featuring dynamic tensors—where output sizes cannot be predicted ahead of operator evaluation—ArenaPlanner::ExecuteAllocations devoured 54.3% of total execution cycles.
Phase 2: Eliminating Low-Hanging Fruit (Caching and Pointer Directness)
Drilling deeper into the flame graphs revealed micro-inefficiencies that static code analysis would likely have missed.
- Caching Constant Tensor Counts:
The functionInterpreterInfo::num_tensors()accounted for 10.4% of total runtime. Because it was wrapped inside a standard iteration loop and implemented as a virtual function calling downstream logic, the system suffered massive repeated overhead. Because the memory arena allocator does not create or destroy tensors during execution, the tensor count remains constant. Caching this value outside the loop instantly eliminated redundant calls. - Direct Array Access:
Similarly,InterpreterInfo::tensor(unsigned long)was executing costly bounds-checking logic inside virtual function calls. By exposing a direct pointer to the underlying tensor array, the team bypassed this redundant safety overhead.
These two minor adjustments dropped overall model execution time by 25% and halved the total cost of the memory allocator.
Phase 3: Refining Allocation Logic and Map Structures
With the initial wins secured, a second profiling session isolated ArenaPlanner::CalculateAllocations as the primary offender, consuming 12.7% of runtime. This function relied on ArenaPlanner::CreateTensorAllocationVector, which dynamically sorted tensors by size to feed a "Greedy by Size" allocation algorithm.

- Map-Based Indexing: Instead of iterating through every tensor in the model to find matches between network nodes, the team implemented a pre-computed map structure. This dropped the cost of
CreateTensorAllocationVectorfrom 4.8% down to 0.8% of runtime. - Conditional Pointer Resolution:
ArenaPlanner::ResolveTensorAllocation—responsible for resetting tensor data pointers post-allocation—was consuming 10.9% of CPU cycles despite many pointers remaining completely static. By introducing change-tracking logic, redundant pointer updates were eliminated entirely, causing the function to vanish from the performance profile.
Phase 4: Overhauling Deallocation and Data Structures
Next, attention turned to SimpleMemoryArena::Allocate and SimpleMemoryArena::Deallocate, which accounted for 7% and 6.8% of runtime, respectively.
Engineers briefly experimented with replacing internal std::vector structures with an std::multimap to speed up insertions and removals. Counterintuitively, the multimap implementation slowed down the arena code by nearly three times. This reinforced a core tenet of systems programming: while tree-based structures boast superior asymptotic complexity ($O(log N)$ vs. $O(N)$), their higher constant factors and poor cache locality often destroy performance when iterating over contiguous blocks of memory.
Instead, the team optimized the vector approach:
- Replaced frequent
std::vector::erasecalls (which triggered expensive internalmemcpyoperations) with single-pass deletions viastd::remove_if. - Introduced
SimpleMemoryArena::DeallocateAfter(int32_t node), tailoring deallocation to match the linear execution flow of neural network graphs.
Phase 5: Purging Inactive Records to Curb $O(N^2)$ Scaling
Even after these fixes, SimpleMemoryArena::Allocate suffered from an inherent $O(N^2)$ complexity scaling issue tied to the Greedy by Size algorithm. As the network executed, historical tracking data for already-processed nodes lingered in memory.

The team solved this by implementing periodic record purging. By stripping out tracking data for tensors belonging to already-executed nodes, the active working set ($N$) was dramatically reduced.
Supporting Data: Before and After the Optimization
The cumulative impact of these targeted C++ refactorings transformed the profile of complex TFLite models.
| Metric / Component | Before Optimization (TF 2.12 & Earlier) | After Optimization (TensorFlow 2.13) | Performance Gain / Impact |
|---|---|---|---|
| Total Memory Arena Overhead | ~54.3% of total model runtime | ~6.0% to 11.0% of total model runtime | ~80% reduction in allocation overhead |
InterpreterInfo::num_tensors() |
10.4% CPU consumption | Eliminated via local caching | Negligible overhead |
ArenaPlanner::CreateTensorAllocationVector |
4.8% CPU consumption | 0.8% CPU consumption | 6x speedup |
ArenaPlanner::ResolveTensorAllocation |
10.9% CPU consumption | Completely removed from profile | Eliminated redundant pointer resets |
| Dominant Bottleneck | Memory Arena Allocation (ExecuteAllocations) |
Fully Connected Matrix Multiplication | Shifted bottleneck back to core math operators |
As evidenced by the final Simpleperf flame graphs, the runtime profile shifted from being choked by framework housekeeping to correctly prioritizing mathematical tensor operations.
Official Responses and Engineering Insights
Reflecting on the engineering hurdles overcome during the project, lead author and Software Engineer Alan Kelly emphasized the unpredictability of performance engineering:

"I was expecting to find that ML operators such as fully connected layers or convolutions to be the bottleneck of this model, and not runtime overhead… This really is as bad as it gets. But Simpleperf made identifying these inefficiencies easy."
Kelly also highlighted the danger of relying on intuition over empirical testing, referencing the failed experiment with std::multimap:
"While this goes against intuition, this is commonly found when optimizing code. Operations on a set or a map have linear or logarithmic complexities, however, there is also a constant value in the complexity. This value is higher than the constant value for the complexity of a vector."
Google’s TensorFlow core team formally integrated these patches into the mainline repository, culminating in their stable release within TensorFlow 2.13. Developers utilizing TFLite on Android, iOS, and embedded Linux platforms inherit these performance gains automatically upon upgrading.

Implications for Edge AI Developers
The successful optimization of TFLite’s memory arena carries significant implications for the broader edge AI ecosystem:
- Unlocking Complex Dynamic Models: By removing the severe initialization penalty associated with dynamic tensors, developers can now deploy sophisticated models—such as transformers and variable-resolution vision networks—on mobile devices without fearing stutter or latency spikes during inference startup.
- Hardware Energy Efficiency: CPU cycles spent spinning in unoptimized memory allocators consume precious battery life on mobile and IoT devices. Slicing runtime overhead by over 40% translates directly into cooler device temperatures and lower power consumption.
- Democratization of Native Profiling: By providing clear documentation and command-line instructions for Simpleperf and
pprof, the TensorFlow team has empowered third-party developers to conduct deep performance profiling on their own custom hardware targets, fostering a more transparent and performant edge-AI community.
As machine learning models continue to grow in complexity while migrating closer to the edge, tooling like Simpleperf—paired with rigorous, data-driven runtime maintenance—will remain vital in ensuring high-performance, low-latency AI experiences for end users worldwide.