Beyond the Benchmarking Crisis: How New Metrics are Resurrecting the Potential of AI ‘Virtual Cells’
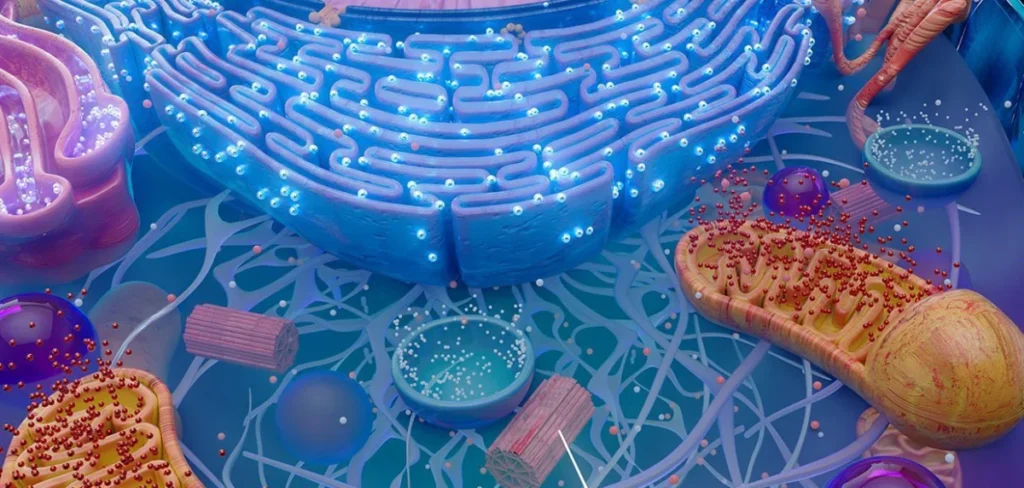
In the rapidly evolving landscape of computational biology, the concept of the “virtual cell”—an AI-driven model capable of predicting how a cell will respond to genetic modifications—has long been hailed as the "holy grail" of drug discovery. By simulating the effects of gene activation or inhibition in silico, researchers hope to bypass the prohibitive costs and time-consuming nature of wet-lab screening.
However, a cloud of skepticism has recently hung over the field. Despite massive investments in deep learning architectures, recent benchmarks suggested that these sophisticated models often performed no better than simple, naive baselines. A groundbreaking study published in Nature Biotechnology, titled “Deep Learning Perturbation Models Can Outperform Baselines on Calibrated Metrics,” authored by researchers at Shift Bioscience and their collaborators, suggests the problem may not be the AI, but the yardstick we are using to measure it.
Main Facts: The Metric Misalignment
The core finding of the Shift Bioscience study is that AI virtual cell models have been unfairly maligned by evaluation metrics that lack the sensitivity to detect biologically meaningful signals. Historically, the field has relied on standard metrics like Mean Squared Error (MSE) or basic Pearson correlations to gauge how well a model predicts transcriptomic changes following a genetic perturbation.
The study demonstrates that these metrics are often poorly calibrated, particularly in datasets where the perturbation signal is subtle. When the evaluation tool cannot distinguish between biological noise and true therapeutic signal, the AI model’s performance appears lackluster. By introducing a "positive-control" framework, the researchers proved that when metrics are adjusted to prioritize perturbation-specific data, the performance of deep learning models significantly improves, outperforming even the most stubborn baselines.
Chronology: From Optimism to Doubt and Back
To understand the significance of this shift, one must look at the recent history of virtual cell modeling:
- The Rise of Generative Biology (2020–2022): With the success of large language models, researchers began applying similar transformer architectures to single-cell RNA sequencing data. Models like scGPT and GEARS emerged, promising to map the complex combinatorial landscape of gene regulation.
- The Benchmarking "Cold Shower" (2023): As more models entered the fray, independent benchmarking studies began to emerge. These studies delivered a sobering conclusion: many of these expensive deep learning models struggled to beat "additive baselines"—simple mathematical models that assume the effect of two genes is merely the sum of their individual parts. This led many in the industry to wonder if AI was truly "learning" biology or merely memorizing data.
- The Shift Bioscience Intervention (2024–2025): Recognizing the discrepancy between the models’ internal complexity and their poor performance on benchmarks, the team at Shift Bioscience initiated a meta-analysis. They questioned whether the metrics themselves were biased against the high-dimensional, nuanced data that deep learning models are designed to capture.
- Publication and Validation (2026): The publication of their findings in Nature Biotechnology formalized the need for a new standard in the field, proposing the "dynamic range fraction" (DRF) as a superior way to evaluate model success.
Supporting Data: Why Current Metrics Failed
The study analyzed 14 distinct genetic perturbation datasets and tested them against 18 different evaluation metrics. The data revealed a systemic failure in commonly used measures.
The "Interpolated Duplicate" Control
The researchers developed an “interpolated duplicate” positive control. This involved taking the average perturbation profile and combining it with an independent technical duplicate, weighted by the strength of the evidence for each gene’s response. This provided a "gold standard" of what a successful prediction should look like.
The Dynamic Range Fraction (DRF)
The team introduced the DRF, a metric designed to measure how effectively a tool separates a positive control (meaningful signal) from a negative control (random noise). Their analysis showed that:
- Traditional Metrics (MSE, Standard Pearson Correlation): These metrics often failed to capture the signal-to-noise ratio in weaker perturbations, leading to "false negatives" where a model’s biological insights were ignored.
- Calibrated Metrics (WMSE, Weighted R², and Normalized Inverse Rank): These metrics consistently showed higher calibration. By emphasizing perturbation-specific signals rather than generic transcriptomic states, these metrics provided a clearer view of model efficacy.
The Landscape of Combinatorial Complexity
One of the study’s most compelling findings relates to the Norman19 vs. Wessels23 datasets. In the Norman19 dataset, where training data covered less than 1% of possible gene combinations, the additive baseline remained king. However, in the Wessels23 dataset—which featured over 10% coverage—deep learning models began to decisively outperform the additive baseline. This suggests that the "failure" of AI in earlier studies was partly a data scarcity issue, exacerbated by metrics that couldn’t handle the complexity of the data that was present.
Official Responses: Insights from Shift Bioscience
Brendan Swain, PhD, CSO and founder of Shift Bioscience, emphasizes that the goal of this research is to restore the promise of in silico biology.
“The promise of in silico perturbation models, or ‘virtual cells,’ is that the same scaling laws will apply—that providing them with ever-increasing quantities of biological data and compute will improve their prediction of real-world experimental results,” Swain explained to GEN. “However, early benchmarks of virtual cell models revealed apparently poor performance, casting doubt on their potential. Our findings show that by using well-calibrated metrics and the right dataset, virtual cell models can generate biologically meaningful insights.”
Swain points out that this is not merely an academic exercise; it is the backbone of their commercial strategy. "We are applying this framework directly in our target identification program, focusing on targets whose inhibition can support both rejuvenation and treatment of age-related disease, giving us a clearly defined route towards clinical development."
Implications: The Future of Drug Discovery
The implications of this research are far-reaching, affecting both the development of future AI models and the strategy of pharmaceutical companies.
1. A New Standard for Benchmarking
The scientific community is likely to adopt these calibrated metrics as the new baseline for publication. This will force developers of virtual cell models to demonstrate not just their model’s accuracy, but its sensitivity to biological signal, effectively ending the era of "black box" performance claims.
2. Scaling the Virtual Cell
With the confidence that deep learning models can outperform simple math, developers can now justify larger investments in data generation. If the "scaling laws" of AI apply to biology, then the current trend of increasing dataset size—as seen in the jump from Norman19 to Wessels23—is the correct path toward fully predictive cellular models.
3. Rejuvenation and Disease Treatment
Shift Bioscience intends to use these tools to identify inhibition targets for cellular rejuvenation. By simulating how specific genes affect the aging process in fibrosis and other age-related conditions, the company can prioritize targets for wet-lab validation that have a higher probability of success. This "filter-first" approach significantly reduces the "trial and error" cost of drug discovery.
4. Moving Beyond Additivity
The study provides a roadmap for moving beyond additive models. It confirms that when the training landscape is broad enough, deep learning models can capture non-linear, emergent biological phenomena that simple baselines simply miss. This is crucial for diseases that involve complex pathways rather than single-gene malfunctions.
Conclusion
The skepticism that once surrounded virtual cell models was a necessary growing pain. By identifying that the problem was, in part, a lack of sophisticated evaluation, the researchers at Shift Bioscience have unlocked a path forward. As the field moves toward larger datasets and more rigorous, calibrated benchmarking, the dream of a digital twin for cellular biology moves closer to reality. For the pharmaceutical industry, this means that the "virtual cell" is no longer a speculative toy—it is becoming a precise, indispensable tool for navigating the complexities of human health and aging.